-
Granular fault isolation: If a CN within
resource-group-acrashes, only the databases assigned toresource-group-aare affected. Databases in other resource groups remain unaffected. - Workload matching & performance optimization: You can tailor resource allocation to match the specific needs of different workloads.
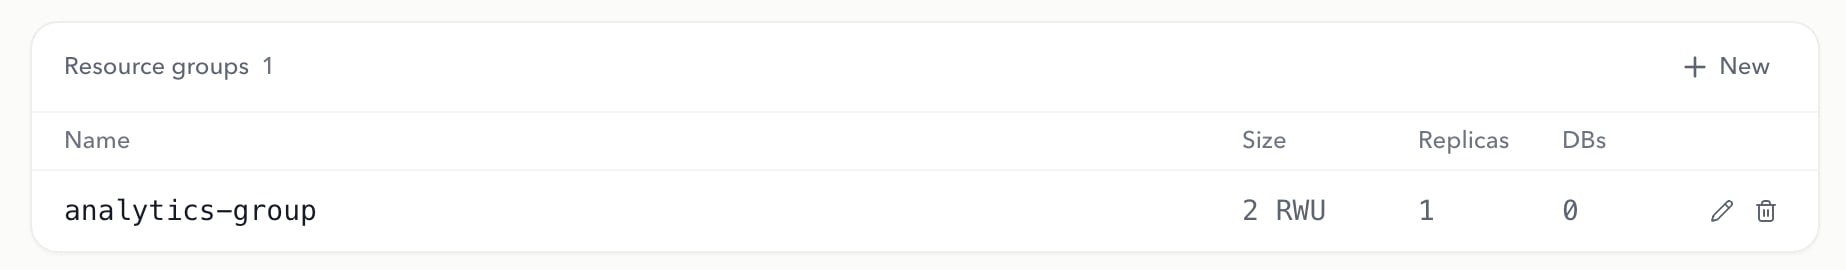
Manage resource groups
Go to the RisingWave Cloud dashboard, open your cluster, and select Resources in the cluster navigation to create new resource groups and manage existing ones.- To add a new resource group, click Create resource group in the top-left corner. Enter the resource group name and select the desired machine size and replica count.
- To access operations for an existing resource group, hover over the desired entry, Delete and Edit buttons will appear on the right.
Manage databases
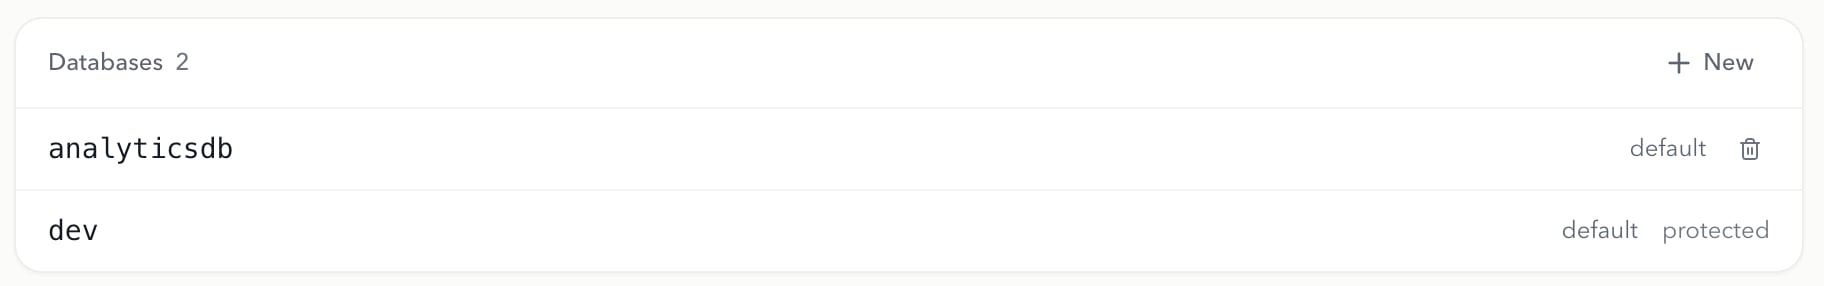
On the same Resources page, use the Databases section to create a new database in a resource group or manage existing databases.- To create a new database, click the Create database in the top-left corner, enter the database name, and select the desired resource group. To create a database on the default Compute Nodes, select the default resource group.
- Hover over a database entry to delete it from its assigned resource group.
Serverless backfilling
The Resources page also includes a Backfilling section where you can enable and configure serverless backfilling for materialized view backfill jobs. When no backfill jobs are running, there are no backfiller nodes.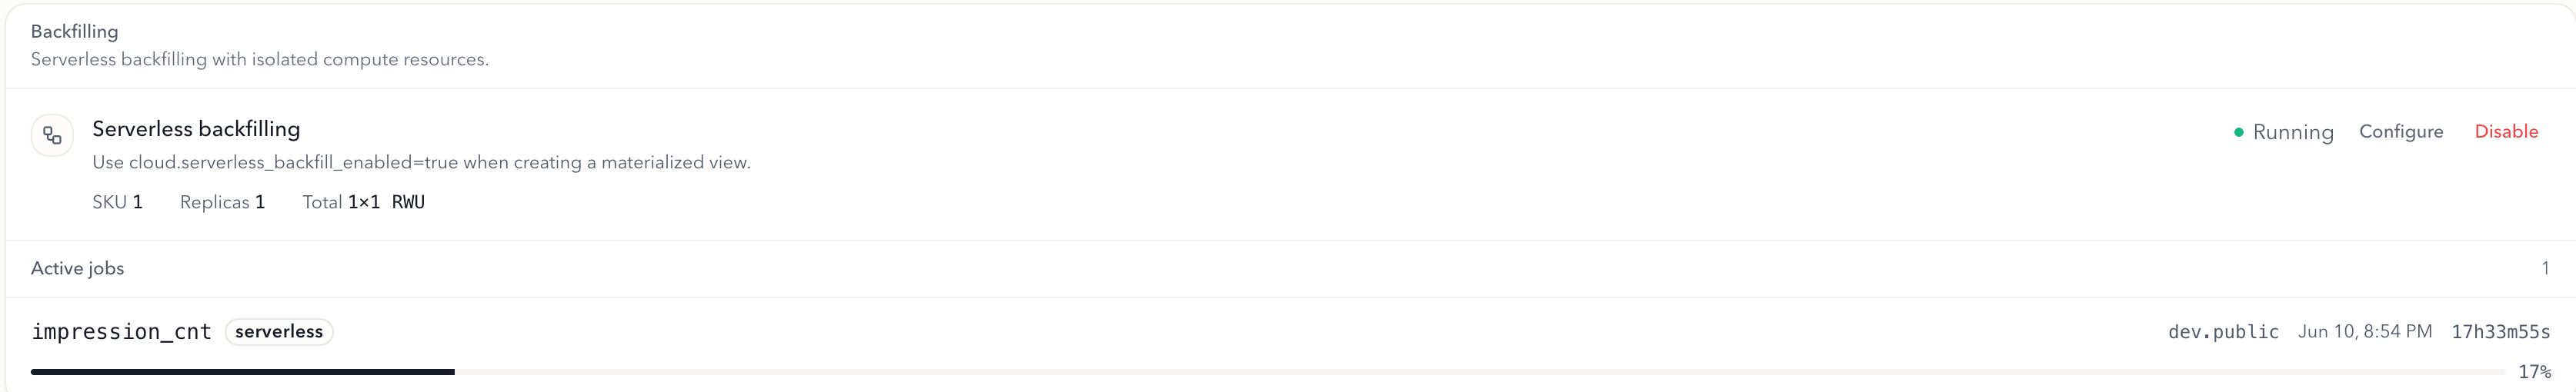
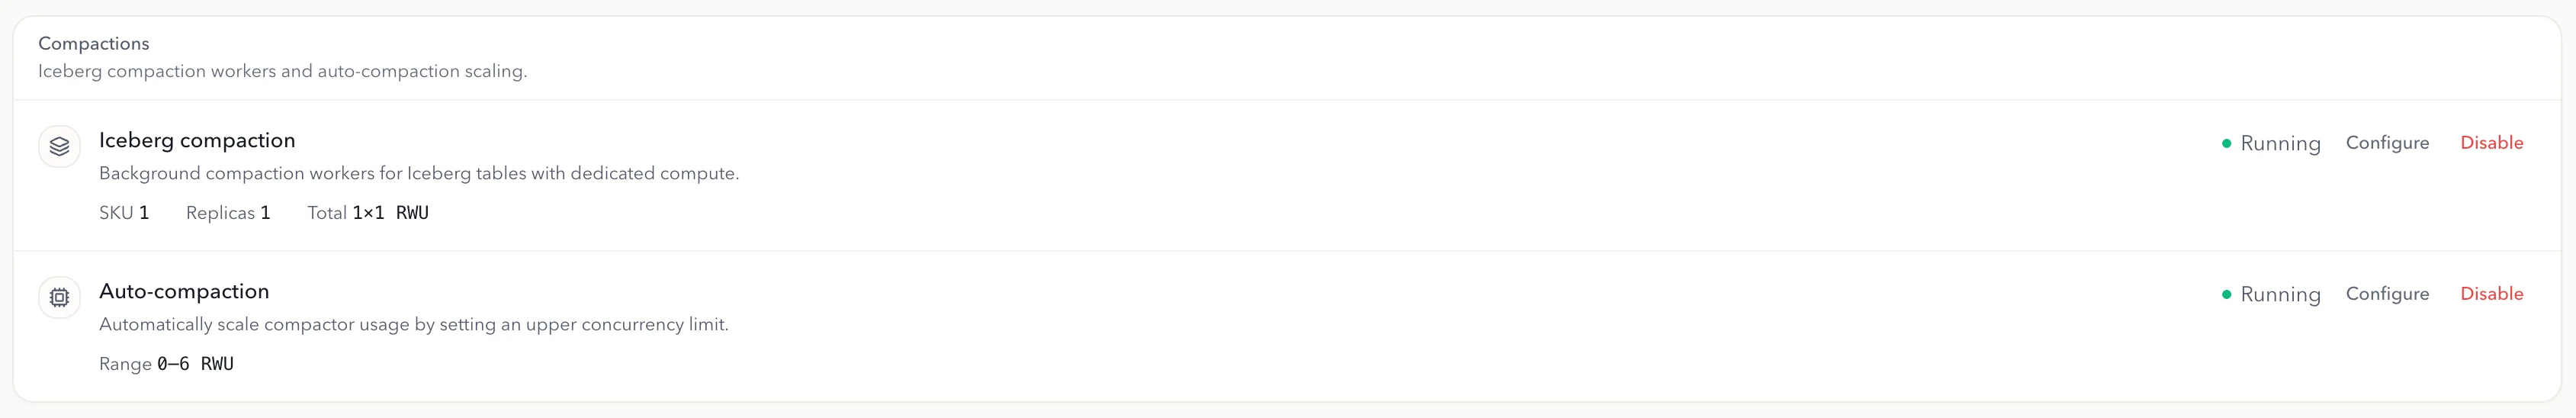
Serverless compaction
The Resources page also includes a Compactions section. There, the Auto-compaction row enables Serverless Compaction, so that RisingWave Cloud automatically scales compactors based on workload, up to a maximum you set, instead of using a fixed Compactor Node SKU and replica count.